News: VAST revolutionizes AI performance – and Aixia delivers the solution
VAST Data has just launched VUA (VAST Undivided Attention) – a new open software technology that greatly improves the speed and efficiency of AI processing. As a VAST partner, Aixia is proud to offer this groundbreaking solution to our customers.
What is it all about?
When AI models, such as large language models (LLMs), generate text and analytics, huge amounts of data (so-called tokens) are created in real time. These tokens normally need to be stored in the server’s GPU memory to avoid time-consuming recalculations. The problem is that the GPU memory quickly becomes full – slowing down the whole process.
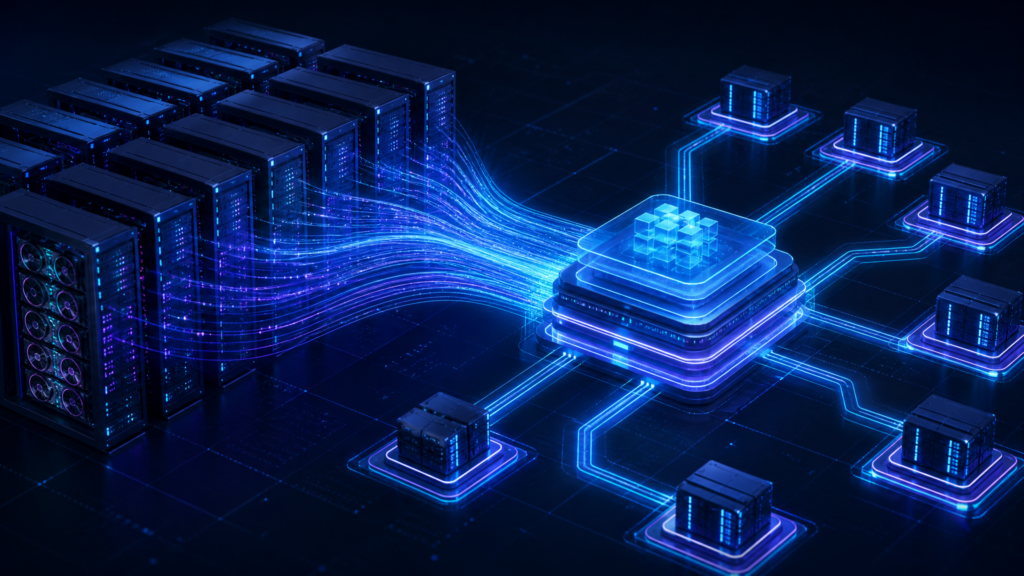
VAST’s VUA solves this by cleverly storing these tokens on lightning-fast NVMe-connected SSDs. This gives GPU servers access to significantly more “virtual” memory, without sacrificing performance. This means AI services can scale up faster, handling more complex queries while reducing both response times and hardware costs.
What does it mean for a CFO?
Shorter response times = better user experience and competitive advantage.
Less need to buy more expensive GPUs.
Increased efficiency and lower TCO (Total Cost of Ownership) of AI infrastructure.
What it means for a technician:
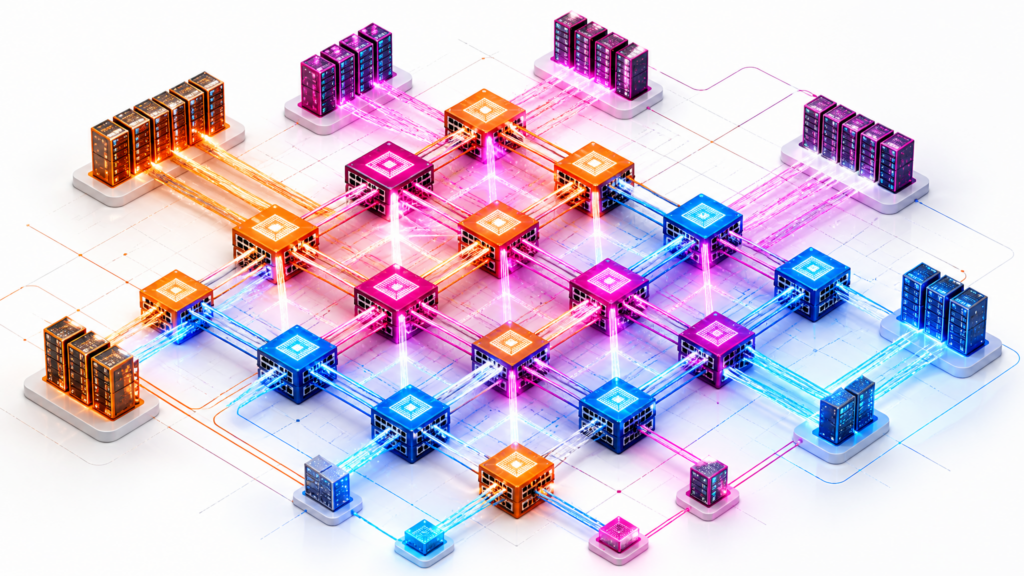
VUA creates a new cache layer between GPU, CPU and NVMe, integrated with GPUDirect.
Global, shared cache that can handle billions of tokens and minimize cache misses.
292% faster token generation in tests – and support for the increasingly large AI models of the future.