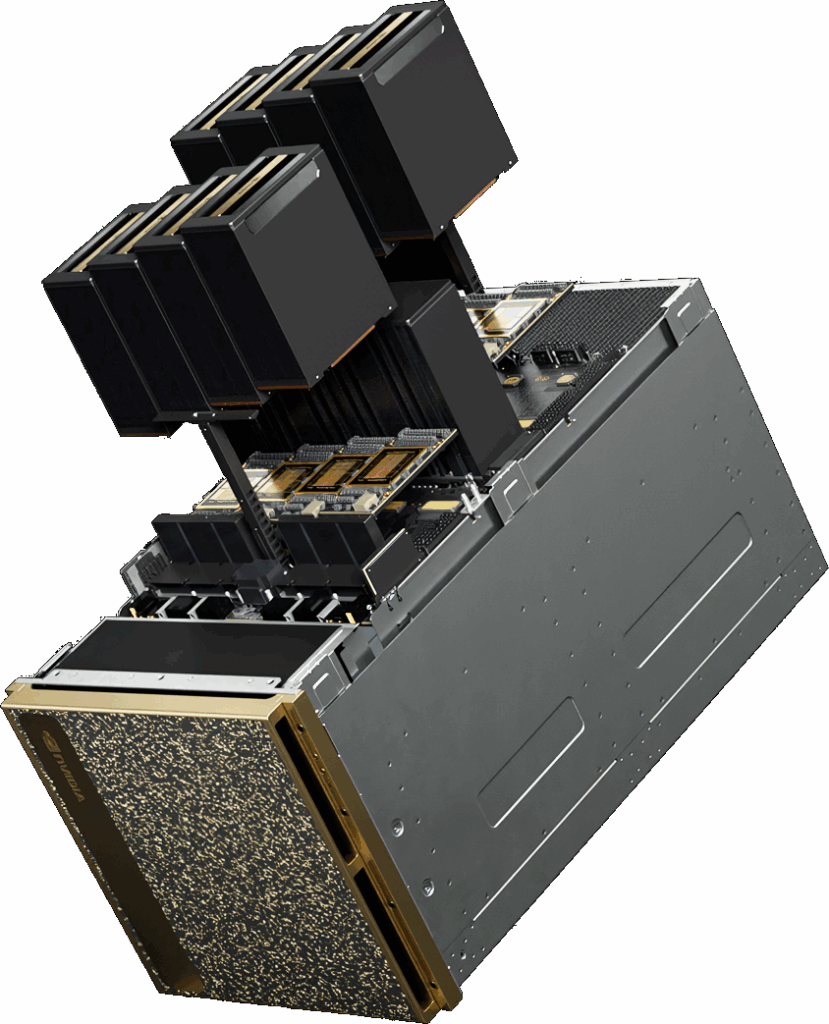
NVIDIA DGX B200 – now available for POC and evaluation
Aixia is proud to announce that we now have the latest generation AI infrastructure, NVIDIA DGX B200, fully operational in our data center. With this investment, we strengthen our position as a leader in advanced AI and HPC solutions in the Nordic region.
A new level of AI performance
Based on NVIDIA’s new Blackwell architecture, DGX B200 delivers up to 72 petaFLOPS for training and 144 petaFLOPS for inference. The system is equipped with eight NVIDIA Blackwell GPUs and a total of 1,440 GB of HBM3e GPU memory, enabling it to handle the most demanding AI workloads, including large language models and generative AI.
Technical specification in brief:
GPU: 8x NVIDIA Blackwell
GPU memory: 1 440 GB HBM3e
CPU: 2x Intel Xeon Platinum 8570 (112 cores in total)
System memory: Up to 4 TB
Storage: 2x 1.9 TB NVMe M.2 (OS) + 8x 3.84 TB NVMe U.2 (data)
Network: 8x NVIDIA ConnectX-7 VPI (up to 400 Gb/s)
Power consumption: ~14.3 kW
Form factor: 10U
The system comes with NVIDIA AI Enterprise and NVIDIA Base Command, providing a complete software stack for AI development and operation.
Proof of Concept – in our data center or at yours
We now offer companies the opportunity to carry out proof of concept (POC) projects with the DGX B200.
In our data center: Test and develop your AI models in an optimized environment with access to our expertise.
On site: Evaluate the DGX B200 in your own infrastructure to see how it integrates into your workflows.
Whatever your choice, we will support you throughout the process, from planning to implementation.
Contact us for more information
Interested in exploring how NVIDIA DGX B200 can accelerate your AI initiatives? Contact us at Aixia to discuss your needs and how we can help you realize them.